
Three blog formats that earn links, and where AI fits
A small marketing team in Singapore asks me the same thing after every traffic review: which blog posts do other sites actually cite, and can ai automation for business carry the production load? Pamela Bump's post for the HubSpot Blog, updated 6 November 2026, gives a partial answer through Irina Nica, the blog's link-building lead: posts backed by original data, thought-leadership and expert interview posts, and foundational ultimate guides. What the post does not cover is the part most SMEs run into, which is that each format fails at a different handover between machine and reviewer. That handover is what this piece maps.
The short answer: pick the data post first if you can gather or compile real figures, because other writers need numbers they cannot produce themselves. Run thought leadership second, using named experts with a topic angle people search for. Build the ultimate guide last, once you already have a body of posts worth linking together. Automation can carry research sorting, drafting, tagging and scheduling; a person still owns the claim, the quote and the publish decision.
What the HubSpot post actually says
Bump writes from her own job as the blog's Audience Growth Manager: referral traffic from other sites is valuable for brand awareness and search authority, and also the hardest traffic to earn, because somebody at another publication has to find the content and judge it worth citing. Her framing is useful for planning because it puts the bottleneck on someone else's editorial decision, not on your publishing calendar.
The three formats Nica names are:
- Data-backed stories. Posts carrying original research, ideally tied to a recent headline or a problem that affects a wide group of readers.
- Thought leadership and expert interviews. Original thinking from someone with standing in the field, or a roundup of short answers from several experts.
- Foundational ultimate guides. Long-form compilations of everything a site has learned about a topic, kept visible so other articles can link to them.
Two tips sit outside that list and matter just as much: original content over reposted material, and promotion effort that is not an afterthought to production.
Data posts: the format that earns citations most reliably
The logic is straightforward. Writers covering a trend need evidence, and a survey, a benchmark or a clean compilation gives them something to attribute. Bump's own example is a Stories preference study, and its after-life shows how far a single data point travels: Buffer's news roundup reported the finding that 70 percent of surveyed people prefer Facebook Stories over Instagram Stories or Snapchat, and Buffer was careful enough to note that the sample was 275 people and drawn from consumers in the United States.
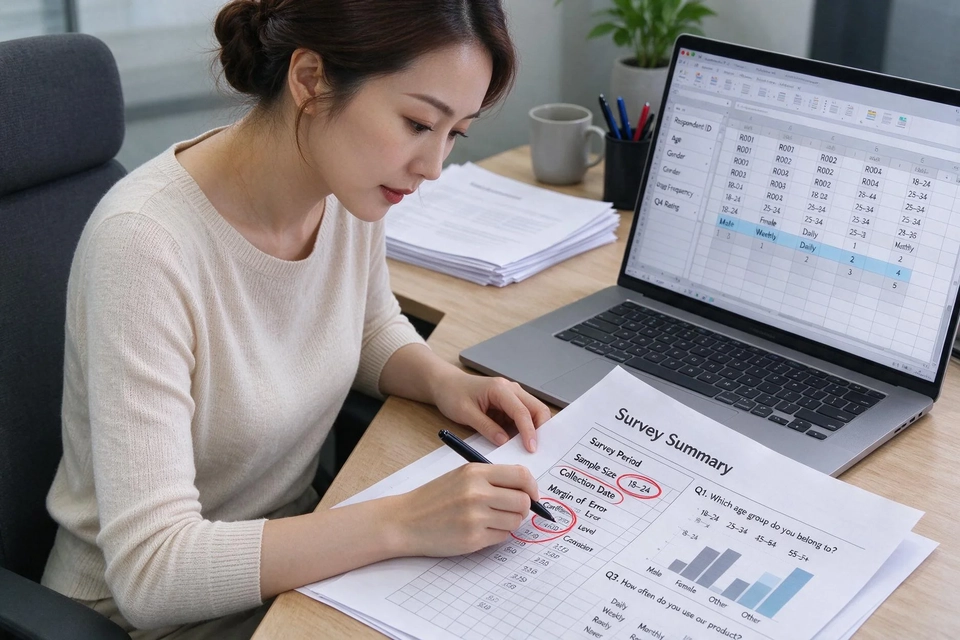
That last detail is the uncomfortable part. Small, single-market samples get quoted widely and are easy for a rival to knock down. When you publish a data post for a Singapore audience, state the sample size, the market and the collection date in the opening section, not in a footnote, because the writer citing you is looking for exactly those numbers.
Where AI helps, and where it does not
Sorting open-ended survey answers, grouping themes, checking that a headline figure matches the underlying table, and drafting the first explanation of what a number means for a marketer: these are repetitive steps that a drafting system handles well. Deciding whether the sample is big enough to support the claim is not. Neither is choosing which number leads the article, because that choice is editorial and visible to every reader who arrives from a citation.
A defensible split, in practice, looks like this:
- AI drafting covers the summary table per question, the commentary draft per figure, and the alternative headline options.
- A person checks the sample, the wording of the claim, and the sentence another writer will quote.
- A person signs off before the post goes live, with the source table attached.
The no-budget alternative
Not every team can run a survey. Bump's fallback is a compilation post: gather several existing studies on one question and explain what they agree and disagree on. The risk here is that compiling is the easiest thing for an automated system to do badly, producing a list of links with a thin bridge sentence between them. The value only appears when you add a judgment the original studies did not make.
Thought leadership: the format that depends on a person
Bump's second type turns on someone with standing in the field saying something specific enough to be quoted. Her team picked topics by search volume first and then matched them to an expert, which is the reverse of how most SMEs brief a piece: they start with the expert's availability and hope a topic emerges.
That reversal is worth copying. Search volume tells you what readers want explained; the expert's experience tells you what you can say that no one else can. When both line up, the post earns links with little outreach, because a journalist or blogger has a reason to point at it.
Roundups as the low-friction version
If a full interview or a guest piece is not feasible, a short-question roundup works: send the same two or three questions to several practitioners and compile the answers with attribution. This is the one format where AI drafting adds the least and where the person adds the most, because the whole asset is the specificity of the answers. Automate the chase, the reminder emails and the formatting. Do not let a system write the quotes or smooth them into sameness.
The human review point
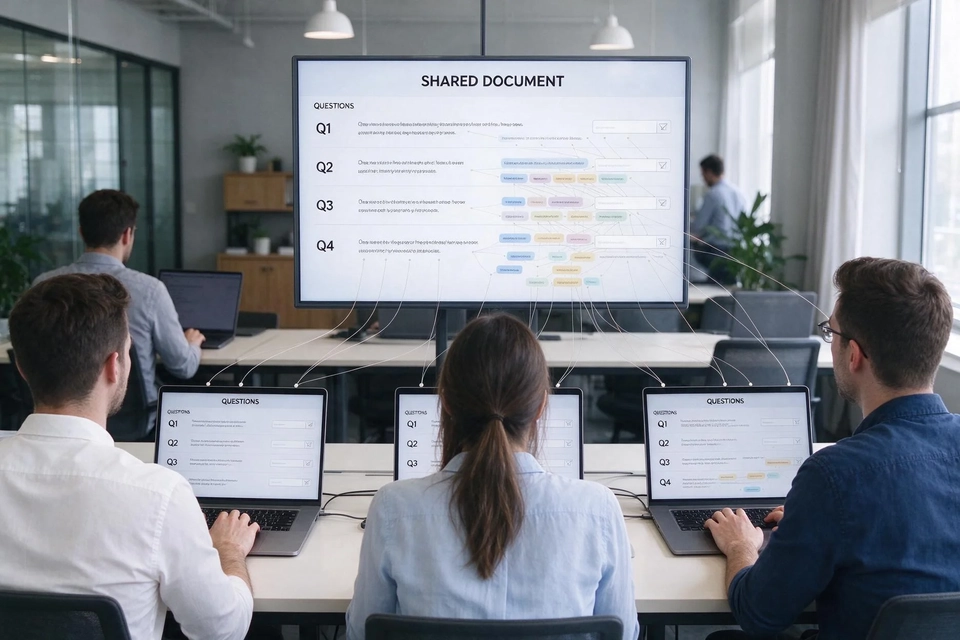
Before anything publishes, a person should confirm three things: that the named expert agreed to be quoted, that the quote is theirs as written, and that the claim in the headline is actually supported by the quote. Getting one of those wrong is a trust problem that no amount of link building repairs.
Ultimate guides: the format that compounds
The third type is a long compilation on a topic the site already covers, kept easy to find so that other articles can use it as a reference. Bump's point, again from Nica, is that not every blog can lead with data, and for some sites the guides are what earn links.
A guide earns its keep as the page a busy writer links to instead of re-explaining something. That is one way ai automation becomes relevant here: the compilation is large enough that drafting support is worth it. That imposes two conditions: coverage wide enough to be a genuine reference, and maintenance frequent enough that it does not describe a product or a platform from three versions ago.
A maintenance checklist
- Re-read the guide every quarter and mark the sections that have aged.
- Keep the internal links from newer posts pointing at it, so the structure stays legible.
- Log every factual change with its date, because a cited page that silently edits its own numbers becomes unciteable.
Where AI helps
Drafting a first outline across a large topic, extracting the sub-questions readers ask, and flagging sections whose examples reference products that have since changed are all reasonable drafting tasks. The judgment call, again, is what to leave out. A guide that tries to cover everything becomes a directory; the value is in the decisions about scope.
A practical order for a Singapore team
The HubSpot post lists formats but does not sequence them, and sequencing matters when a team has one content writer and a budget in the low thousands a month. The order I would suggest is driven by what you can verify, not by what looks impressive.
| Format | What you need first | Where AI drafts | Where a person decides |
|---|---|---|---|
| Data post | A dataset you own, or two to three credible studies to compile | Sorting, tables, first commentary | Sample adequacy, the lead figure |
| Expert post | A named practitioner willing to be quoted | Outreach chase, formatting | The quote and the headline claim |
| Ultimate guide | A body of existing posts on one topic | Outline, sub-question extraction, age check | Scope, what gets left out |
Run one format at a time. A team that starts three at once usually ends up with three thin drafts.
The cost of getting the order wrong
Starting with the guide is the most common mistake, because it feels like the biggest asset. A guide built before you have data or expert commentary tends to restate what is already on the first page of search results, which gives another writer no reason to cite it. Starting with the expert post when nobody will go on record produces the same outcome, a page of general advice.
How Topkee builds this into a workflow
This is where the AI automation conversation turns concrete for a marketing lead. Topkee AI Agent is a platform for deploying ready-made professional roles, which Topkee calls Bot Teams, that automate business workflows; its capability catalogue groups Skills, Plugins and a set of Bot Team job templates built around concrete jobs.
One of those templates is the SEO Bot Team, an automated SEO content and publishing support system. It monitors industry news through PageWatch, which reads new pages and changes via sitemap or fixed URLs, writes keyword-quota articles combined with product knowledge, and routes them into YIS drafts or scheduled publishing. What comes out is linked articles plus the keyword records, content index and publishing plan that keep them accountable. That maps closely onto the data-post and guide formats above, where the repeatable work sits in gathering sources and drafting the first pass.
The governance layer is the part that answers the handover question. Important actions, from spending to publishing and key configuration changes, pass through human Approvals, and run records link task lists with evidence; deployed instances use short-lived tenant JWTs rather than long-lived API keys. The writing skill behind the articles, SEO Insight Writer, defaults to shadow mode, which means it only writes when explicitly switched live, and it flags an article do_not_publish when a second independent source is missing. YIS Feed converts a finished article into a channel post with supporting images, then schedules it, and it defaults to a draft: scheduling is an explicit publishing authorisation, and scheduling is not the same as published.
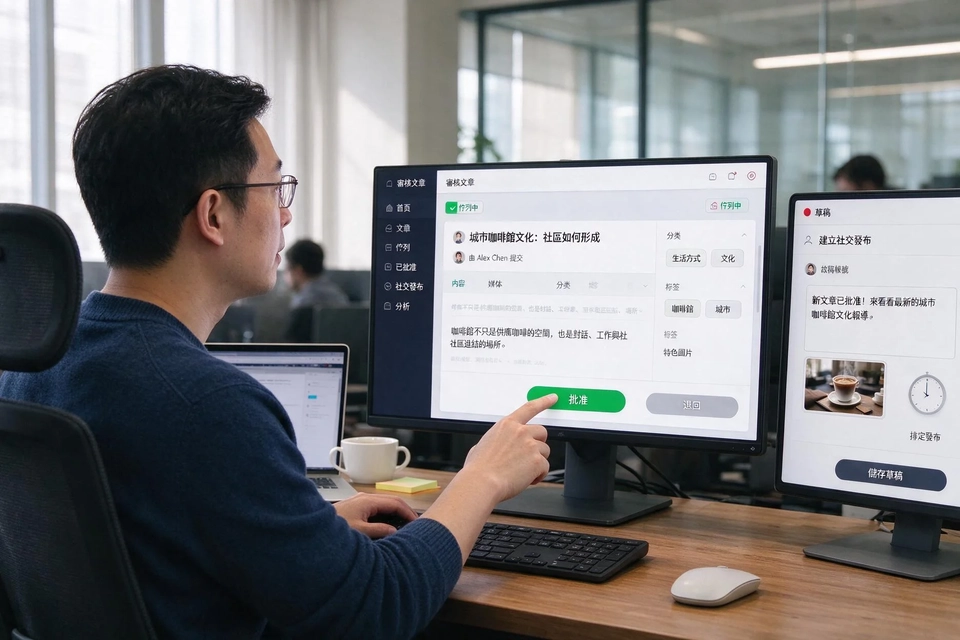
Finally, the distribution side matches the channel mix Bump describes at the top of her post. YIS collects business materials and builds content calendars from them, while YIS Feed turns articles into posts for email, social and the other channels you already run. That is the non-organic traffic path, handled by a system rather than by one person remembering to post, and it is the operational side of ai automation most teams underestimate.
Two boundaries are worth stating plainly. The knowledge base behind these notes says content quotas do not equal authoritative backlinks, media placements or indexing promises, so a Bot Team raises production capacity and consistency, not a guaranteed link count. The blog framework method it documents (customer solution research, data collection, product updates) is a structure for deciding what to publish, not a substitute for the editorial judgment each format above depends on.
Recommended next action
If you are weighing this up, the cheapest test is to take one high-frequency task, such as turning a weekly roundup of industry pages into draft outlines, and run it with a reviewer in the loop for a month. Topkee's own suggested rollout follows that order: pick the task, connect the data and services, pilot it on real work, then reuse what worked. You can look at how automation is applied to paid media first in two walkthroughs of the same pattern: Google Ads AI tools for Ramadan sales and UCP optimisation for retail Google Ads both pair a system draft with a human approval step.
For the link-earning side, decide the format order from the table above and write down, for each format, the one thing your team will not let a machine decide. That sentence is the difference between a workflow and a machine that publishes, and it is the practical test of any ai automation for business rollout.
FAQ
Are these three post types the only ones that earn backlinks?
No. They are the three the HubSpot Blog's link-building lead names from experience, and the post itself allows that for some sites ultimate guides are the main earner. Treat them as a starting shortlist and test each against your own referral traffic.
How many backlinks should a data post get?
HubSpot's post does not give a benchmark you can plan against, and this article will not invent one. What you can control is whether the post states its sample, market and date clearly enough for another writer to cite it without further checking.
Can AI write a thought leadership post on its own?
It can draft, structure and format one, but the asset is the expert's original view. A piece with no named, consenting expert behind it is not thought leadership, whatever the length.
Does publishing more SEO articles automatically bring links?
No. Topkee's knowledge base states that content quotas do not equal authoritative backlinks, media placements or indexing promises. Volume helps coverage; the link comes from someone deciding your page is worth citing.
What should be checked before an automated post goes live?
At minimum: every number traces to a verified source, any quoted person consented to the wording, the headline claim matches the body, and the publish action itself went through an approval rather than a scheduled default. These are the review points an ai automation setup should encode as gates rather than reminders.
Sources
- Pamela Bump, "3 Types of Blog Posts That Earn the Most Backlinks, According to HubSpot's Link-Building Expert", HubSpot Blog, 2026-11-07. https://blog.hubspot.com/marketing/blog-posts-that-earn-the-most-backlinks
- "Understand HubSpot's traffic sources in the web traffic analysis tool", HubSpot Knowledge Base, 2026-08-01. https://knowledge.hubspot.com/reports/understand-hubspots-traffic-sources-in-the-traffic-analytics-tool
- Heather-Mae Pusztai, "Social Media News Roundup: Facebook's Future, Popular Stories, + More", Buffer, 2019-10-14. https://buffer.com/resources/social-media-news-october-2019/
- "Complete SEO Starter Pack: Get Your Website and Blog Ranking", HubSpot, 2026-08-20. https://offers.hubspot.com/seo-starter-pack